Showing posts with label Programming. Show all posts

Wednesday, May 20, 2015

KeePass2 and Gmail

It's been a while since I posted, but with a good cause: We just had our second child a few weeks ago!

The other day, Google decided to change Gmail's login screen to be in three parts (two for those without two-step authentication): 1. Username 2. Password 3. Two-Step Authentication. This is annoying because I use KeePass2 with auto-type, and the new pages interfere with the auto-typing mechanism.

Today I decided to solve that issue, and I'm posting it here to share with anyone else who may also have the same problem. Here are the steps:

  1. Open up the Gmail or Google Apps email account you want to change ("Edit/View Entry" on the context menu, or hit Enter when the entry is selected).
  2. Go to the Auto-Type tab.
  3. Select "Override default sequence" option.
  4. The field should initial have (without quotes):

    "{USERNAME}{TAB}{PASSWORD}{ENTER}"

    Replace that with (without quotes):

    "{USERNAME}{TAB}{ENTER}{DELAY 2000}{PASSWORD}{TAB}{ENTER}"

  5. Test in your favorite browser. Adjust the "{DELAY mmmm}" parameter by replacing "mmmm" with a different numeric value. This is in milliseconds, so a value of 1000 is 1 second.

The "{DELAY 2000}" parameter is the key to fixing the issue. Since there is a new page in between the username and password, we need a delay to let the page load before typing the password.

For more information on the auto-type feature and the parameters that can be used, see the KeePass documentation here:

http://keepass.info/help/base/autotype.html

Don't forget to tag your Gmail account as an OpenSSL account (add "OpenSSL" to the description) while you're at it!

Tuesday, November 25, 2014

Strange SAS Error Message

I spent far too long trying to debug a strange error message in SAS. The solution ended up being aggravatingly simple, but arriving at the solution was not. So I wanted to share the problem and solution. (I discovered this issue using SAS 9.1.3.)

MPRINT(TRANSPOSE): proc datasets nolist;
SYMBOLGEN: Macro variable OUT resolves to lib.table_name
NOTE: Line generated by the invoked macro "TRANSPOSE".
161 modify &OUT; label &NEWVAR = "&NEWLBL"; quit;
               _
               200

MPRINT(TRANSPOSE): modify lib.table_name;
NOTE: Line generated by the macro variable "OUT".
161 lib.table_name
    _______________
    22
NOTE: Enter RUN; to continue or QUIT; to end the procedure.

SYMBOLGEN: Macro variable NEWVAR resolves to count
SYMBOLGEN: Macro variable NEWLBL resolves to count: prevalence
MPRINT(TRANSPOSE): label count = "count: prevalence";
MPRINT(TRANSPOSE): quit;

ERROR 200-322: The symbol is not recognized and will be ignored.
ERROR 22-322: Expecting a name.

NOTE: Statements not processed because of errors noted above.
NOTE: The SAS System stopped processing this step because of errors.
NOTE: SAS set option OBS=0 and will continue to check statements. This may cause NOTE: No observations in data set.
NOTE: PROCEDURE DATASETS used (Total process time):
      real time 0.00 seconds
      cpu time 0.00 seconds


If you start looking where the error statements start and look down, you'll miss the true source of the error.

So for those not familiar with PROC DATASETS, one of the options on the PROC DATASETS statement is the LIBRARY= option. It defaults to WORK. So this PROC DATASETS is looking only in WORK for the dataset lib.table_name. Since "lib." is not a valid part of a table name (and just the table name), it's not parsing it correctly, resulting in an error.

The error seems to cause the SAS code parser to trip and read the rest of the code incorrectly, and it looks like the following step is where the error occurs. However, it's actually the earlier step ("modify &OUT" or the resolved code, "modify lib.table_name").

The lesson is twofold: 1) Don't try to use an output library with the table name (e.g., "lib.table_name") when the LIBRARY= option on PROC DATASETS is not used. 2) Don't write a macro where an output data set can be specified (e.g., OUT=) and use PROC DATASETS without checking whether the user specified an output library. Alternatively, don't use PROC DATASETS. (There are some advantages to PROC DATASETS, so don't throw the baby out with the bathwater!)

I wasted a lot of time on this since I thought the macro could handle any type of input/output specified, but apparently that is not true. The solution for me was to remove the "lib." from the OUT= argument to the macro ("&OUT"). Since PROC DATSETS was looking in work, it found it after I made this "correction".

Wednesday, January 29, 2014

Bad SQL Writing Put to Good Use

There's a certain style of writing SQL that I really don't like. Here's an example that pulls names and addresses for people in Wisconsin and Illinois:

select p.name, a.address
from person p, person_address pa, address a
where p.person_id = pa.person_id
and pa.address_id = a.address_id
and a.state in ('WI', 'IL')
;


Basically, the author has stacked all the tables into the FROM statement, and specified how they join on the WHERE statement. This creates confusion about how the tables are intended to be joined as well as mixing actual filter criteria with the join conditions. However, it works, since the code results in inner joins between all tables, and that was okay.

My preferred style is like so:

select p.name, a.address
from person p
left join person_address pa
on p.person_id = pa.person_id
inner join address a
on pa.address_id = a.address_id
where a.state in ('WI', 'IL')
;


It's a bit more verbose, but that helps the reader. This style splits out the tables into different statements and results in clearly indicated join types and join fields. It is clear to a reader of the code the intention of joining each table. The filter criteria are located in the WHERE statement without any other statements to confuse them with. There are still cases where the result may not be as expected based on the filter criteria, but it's easier to debug.

Overall, the first example is a confusing style to use, and it can cause trouble if the joins were intended to be outer joins and were not, because the style does not have a way to specify outer joins. (LEFT JOIN is short for LEFT OUTER JOIN, which means, basically, return all records from the first table, and any data that matches in the next without missing any records from the first.)

The other day, though, I encountered a great way to use this potentially error-prone style in a way that is actually very useful.

I wanted to generate a master list of all potential ZIP codes in the US, and then filter out ones that are not in use or are otherwise invalid. I started by creating a small table with 10 rows that consist of 1 column with the numbers 0-9.  With no loop statements available in SQL, I wrote this table like so:

create temporary table num (n int);
insert into num values (0);
insert into num select max(n)+1 from num;
delete from num where n > 9;


That last statement is just in case I ran it too many times. I was even too lazy to write out 1-9, instead just repeating the max+1 code 9 times. It's a bit over-the-top, but it works.

To get my "master" list of ZIP codes, I joined the table to itself 5 times, one for each character in the ZIP code (because they can start with 0s, they should be treated as characters, not numbers!). Here's how:

create table master_zip as
select n1.n||n2.n||n3.n||n4.n||n5.n as zip
from num n1, num n2, num n3, num n4, num n5
order by 1
;


Simple, isn't it? Essentially, this just makes a big Cartesian product of the table with itself times 4. There's no WHERE statement, because there's no need to join on anything. (If a system required it, I would just write "where 1=1".) This generates 100,000 records. That's about 58,000 too many, according the US Postal Service, so we need to delete some of those that are not in use. But that process is for another time.

Using a style that I usually do not recommend or warn against was interesting and useful, but it requires knowing a bit more about how these things work. Had I run this last bit of code on a larger data set, it would have caused a lot of problems, like running out of disk space or RAM. So use this style sparingly and carefully!

Friday, December 6, 2013

Happy Birthday to Me, From Me, Sorta

A few years ago, I worked at a company that uses SAS, and has a SAS server set up. I figured out that scheduling a SAS job was a bit clunky in Windows, so I mitigated the problem by setting up a SAS program run any tasks on a schedule, and then scheduling that task in Windows.

Since the program was evaluating dates and times to schedule tasks, I threw in a few happy birthday emails as a joke. A few years later, I woke up today to find this in my email inbox:
Chris,

Happy birthday! I hope you have a great day!

Sincerely,

The [Company Name] SAS Server
Well, I'm surprised that's still running! At least it wasn't sent from my old account on that server: they had at least updated who was running the job. But I'm a bit surprised they still let this go. Either they don't realize that the scheduling code contains the happy birthday emails, or they don't mind.

As a side note, the program also ran CheckLog, which reviews the SAS log output for issues, and it emailed the author about the status of the program. This was better than running CheckLog within a program, since the program could crash before it even got to the end, resulting in no status update when it was the most critical.

At any rate, it's good to  know what I wrote is still useful, even if it contains a bit of questionable code!

Tuesday, November 12, 2013

What is a Data Scientist?


Today on Quora, someone asked, "What are some software and skills that every Data Scientist should know?". I wrote the following as a response, reflecting on my current position and the role I play.


I started adding post-it notes with sub-titles to my name/title tag on my cube, as sort of a joke regarding the question, "What is a Data Scientist?".

Here's the current list:
  • [Client] Analyst
  • [Product A] Analyst
  • Financial Analyst
  • Sales Analyst
  • Contract Analyst
  • Quality Assurance Analyst
  • Call Center Analyst
  • Data Surgeon (aka, data mining with the intent to figure out what's wrong)
  • Data Diagnostician (alternative of above, maybe with no details to examine)
  • [Product B] Analyst
  • Database Developer
  • Bug Finder (as in software bugs)
So it would appear from this list that there isn't a lot of data science going on. And that's partially true.

Each of our clients has its own relational database, so we do "meta-queries" to access them one by one in order to answer a question. That's sort of data science like. Eventually, though, we're going to have one master database with all clients that will cascade into individual databases. So our "meta-queries" will be obsolete.

We deal with a lot of "big data" too, but it's usually not that big of a deal. Even with relational databases, it's okay. Some queries may take a little longer (30-60 minutes), but that's rare. We have some machine learning tasks that pull in massive training data sets, so at that point you have to be more careful about "big data" problems like running out of RAM or disk space. But it can be handled, and rather simply.

What I really wish I could do more of is machine learning, and while I've accumulated several ideas that would enhance products or help us make better decisions in the year I've been a Data Scientist, these other tasks take up most of my day.

In the end, I write a lot of SQL, use the Linux command line moderately, and report on data in Excel spreadsheets. I use Python occasionally to write scripts. And I'm always learning something new (new SQL techniques, Python libraries, Linux command line tools, etc.).

Wednesday, December 12, 2012

An Amended Quote

Today on The Writer's Almanac, Garrison Keillor read a quote by Gustave Flaubert:
"I spent the morning putting in a comma and the afternoon removing it."
I thought this could use some amending for programmers:
I spent the morning putting in a parenthesis and the afternoon removing it.
Or for you SAS programmers:
I spent the morning putting in a semicolon and the afternoon removing it.
How about SQL:
I spent the morning putting in a column and the afternoon removing it.
Or if you write HTML:
I spent the morning putting in an escaped ampersand and the afternoon removing it.
Why not Python:
I spent the morning importing a library and the afternoon removing it.
Essentially, though, these all boil down to:
I spent the morning putting in (an) arbitrary character(s) and the afternoon removing it.
For all you programmers during this holiday season: May your parentheses be matched (your quotes too!), special characters escaped, and code executable on the first run.

Tuesday, June 19, 2012

An Attempt to Answer a Quiz Question

Kyra heard the NPR Weekend Edition Sunday puzzle on the radio the other day: "Think of a common French word that everyone knows. Add a 'v' (as in 'violin') to the beginning and an 'e' at the end. The result will be the English-language equivalent of the French word. What is it?"

I thought, well, I don't know French, but I do know how to write a Python program that can look up the answer. Unfortunately, the puzzle appears to be a bit of a trick. I thought as much as I was writing the code. I was thinking, "I bet some people are going to be mad about the answer, because the question was worded in such a way as to be tricky."

At any rate, the code definitely does not result in the right answer, but it was a good exercise for me. First, I had to find two dictionaries robust enough to have a lot of words in English and French. Then I had to find dictionaries: I located the Debian operating system dictionary on my local computer, did a search in the package manager Synaptic for the French equivalent and any other English dictionaries that might help, and downloaded both. (The English alternative is labeled "insane" for its size, which "possibly contains invalid words (as well as words that are very uncommon)." [1])

Next I had to convert certain French characters into their English equivalent. To answer the question, I looked up all English words that start with "V" and end with "E", then removed those two letters, looking up the "word" in the modified French dictionary. It didn't work, as can be told from its output:

a
a
ah
aire
alu
an
ange
ares
as
er
erg
es
es
il
o
t

Yep, those are definitely not the answers. Some, when you add V and E back, aren't  even really English words. "Vte"? What is that? Oh, and I think A is listed twice due to the missing diacritics.

For anyone who's interested, I posted the code online. (It's not pretty posting a lot of code on Blogger, so here it is in a document.) Keep in mind I'm a new programmer, so I might not have done this task very elegantly. It is a short piece of code, though, and it could have worked.

One other note: If you attempt to run it, it may not work on your system. It's designed for Debian GNU/Linux, as it relies on dictionaries in a Debian system and it uses the "/" as the directory delimiter. Additionally, the "insane" dictionary makes it run a bit slow, and I did nothing in the code to help with that, like buffering the file, so you could run out of RAM or peak the CPU. It works on my system, which is all that mattered to me at the time.

Of course, a more robust program should be more careful and actually take user input in some fashion. Perhaps look up words that with other characters or use different languages. As it is, it's more of a "script" that does one thing and non-interactively. In any case, it doesn't even return the "right" answer!

[1] http://packages.debian.org/squeeze/wamerican-insane

Tuesday, January 10, 2012

SCAPROC Bug in SAS

In my current position, we have a macro set up to run other programs, and it outputs a copy of the code, an MPRINT file, and the log. It also re-runs a project-specific autoexec to keep a copy in the log, analyzes the log for errors and warnings (using something other than my CheckLog macro), and it collects and outputs metadata. The part that finds and outputs metadata is called PROC SCAPROC. Here is how SAS describes it:
The SCAPROC procedure implements the SAS Code Analyzer, which captures information about input, output, and the use of macro symbols from a SAS job while it is running. The SAS Code Analyzer can write this information and the information that is in the original SAS file to a file that you specify.
Sounds nifty, right? Well, I've noticed some odd issues with it over time, and only recently was I able to put my finger on one of its problems.

The arrangement of code that results in the issue is rather odd and easily avoided. Nonetheless, in case anyone has encountered the problem, I thought I would post code to replicate the problem here. First, run this part in a new SAS session:

/* Set the base directory */
%let dir=%sysfunc(pathname(work));

/* Create a new folder */
%sysexec mkdir "&DIR.\lock";

/* Assign a library with a locked data set */
libname lock "&DIR.\lock";

/* Create a locked data set */
data lock.locked(pw='asdf1234');
    x=1;
run;

So we've created a new library with a locked data set based on our work library. Now, try out SCAPROC with the following code and see what happens:

/* Copy the CARS data set */
data cars;
    set sashelp.cars;
run;

/* Create a view */
proc sql;
    create view badview as
    select type
    from cars
    ;
quit;

/* Remove type from the data set */
/* This makes the view (i)nvalid */
data cars;
    set cars;
    drop type;
run;

/* Start PROC SCAPROC */
proc scaproc;
    record "&DIR.\lock\scaproc_out.txt" attr;
run;

/* Copy data out of SASHELP */
data test;
    set sashelp.vcolumn(where=(libname="WORK"));
run;

/* Write out SCAPROC */
proc scaproc;
    write;
run;

And now we've created a view from a SASHELP table and made it invalid by removing the column that the view uses in its definition. We started SCAPROC and attempted to use another SASHELP table that contains metadata about all of the columns available to SAS. Did you get a pop-up for a password at this point? If so, that's part of the bug. Next, SCAPROC ends. Take a look at the log: are there some error messages? There should be at least one regarding the invalid view. Now take a look at the output of SCAPROC. It's a bit inflated for such a small program, especially if you have a large number of libraries assigned. Assign a bunch of libraries and try the code again, and it will explode.

The issue here has a few parts: First, we need an invalid view and a fully password-protected data set. Second, we need to run SCAPROC; and finally, we need to run a DATA step against SASHELP. The invalid view causes SCAPROC, upon encountering the SASHELP.Vcolumn data set, to consider all data sets listed in the table as input to the program. Interestingly, if you replace the DATA step with SQL, the issue disappears, except for the error regarding the invalid view. Dropping the use of SCAPROC also removes the problem (obviously).

Why did the password pop-up appear? Since SCAPROC considered all data sets as input, it attempted to collect metadata on the locked data set. A sub-bug of the main bug is that SCAPROC should not query locked data sets, since it won't know the password. If you were to run it in batch mode, there wouldn't be anyone around to enter a password. Another sub-bug is that the DATA step somehow tells SCAPROC that all available data is an input.

As a consequence of this issue, we had a program run where the metadata output of SCAPROC that contained variable names was a SAS data set with 5.1 million rows at 972 MB. That was huge, and the SCAPROC output file was also huge, at 751 MB. And it's just a text file - no SAS header, column structure, anything!

I submitted the bug set to SAS, but in the meantime if anyone encounters this issue, the easiest way to fix it is to either fix the broken views, replace the DATA step with SQL, or both. Good luck, and please let me know if you encounter the issue yourself, or any related issues!

Wednesday, January 4, 2012

SAS Global Forum

I'm a SAS programmer, and I've always wanted to attend one of those big SAS conferences. So this year, when I heard about the SAS Global Forum, I applied for a grant from the University of Wisconsin and submitted two papers to present at the conference.

A few weeks ago I heard that I won the grant, and just last week I found out that both of my papers were accepted by the conference organizers. I'll be presenting both papers in the Coder's Corner section, with the following titles:

An Advanced, Multi-Featured Macro Program for Reviewing Logs
Standardized Macro Programs for Macro Variable Manipulation

If you plan on attending and you happen to follow this blog, please feel free to stop by and say hello! If not, I'll post the links to the papers as soon as their available from the conference organizers. For more information about the conference, go to http://support.sas.com/events/sasglobalforum/2012/index.html.

Hope to see you there!

Monday, December 5, 2011

A SAS Macro to Convert Text to a Persistent ID

I was working on a project in which we usually carried forward a code and a description for every category to make it easier on coders to select a desired category using an ID rather than the long and sometimes-changing description. I found a particular category in which no ID existed, and there were no similar categories that I could use as the basis for a new ID. So what could I do?

In a previous position, I had the same problem crop up, and I solved the problem by doing the following:
  1. Extract one character at a time from the original categorical variable (e.g., 'A').
  2. Convert the character to its binary representation (e.g., '01000001').
  3. Convert the binary representation to the numeric value (e.g., 65).
  4. Sum the final value of each character (e.g., 'ABC' = 65 + 66 + 67 = 198).
Combined, these steps only take up 3 lines of code (excluding the data step code):

do _i_=1 to length(Category);
  ID + input(put(substr(Category, _i_, 1), $binary8.), binary8.);
end;

And the process can be run as a macro program:

http://sas.cswenson.com/downloads/macros/TextID.sas

Note: Run the code in test mode (e.g., %TextID(data, var, test=Y) ) to see each step broken out into separate columns.

The result is a unique ID that will never change for the particular configuration of characters. Keep in mind, however, that the ID is not only character-sensitive, but case sensitive, so "Category" is not the same as "category". To avoid this problem, force the category into upper- or lower-case using the UPPER or LOWER functions.

Using this process, we were able to add a constant, unchanging ID for each category. The ID will not vary depending on the number of categories, the time at which the code is run, or any other variable (other than user-error, if the categories are typed by hand!).

If anyone uses this process, please let me know what you used it for! Oh, and it would be nice if you gave me credit, too!

Saturday, November 26, 2011

64bit GNU/Linux and Webcams (Logitech Quickcam Express)

I've been trying to get  Skype to work on my home PC, which has 64-bit Debian GNU/Linux installed. I came across the following article, which, with a slight modification, worked perfectly.

https://www.martineve.com/2011/09/25/64bit-gnulinux-and-webcams-logitech-quickcam-express/

Here are the instructions with the modification:
  1. As a superuser...
  2. For each 32-bit application, create a script in /usr/bin consisting of the following code.
  3. Name the code APP-camera-fix, where APP is the software to patch (e.g., skype-camera-fix).
  4. Mark the code as executable (I do this in Nautilus via the properties menu).
  5. Change each shortcut to the application to the script you just made (e.g., change the Skype shortcut to /usr/bin/skype-camera-fix).
  6. Test it out by opening Skype and testing the camera in the Options menu.
Code:

#! /bin/sh
LD_PRELOAD=/usr/lib32/libv4l/v4l1compat.so skype

The modification is to simply add "32" to the /usr/lib path. Works perfectly!

Wednesday, November 23, 2011

Check the SAS Log from a Windows Context Menu

Have you ever wanted to check a SAS log from the Windows context menu? Well, now you can with a new script I developed using my CheckLog macro. Here's how:
  1. Download the CheckLog SAS macro and save it to a permanent location.
  2. Download the CheckLogSendTo.txt file.
  3. Open the file and replace the value of the variable CheckLog with the location of the CheckLog SAS macro.
  4. Save the file.
  5. Change the extension of the file to "vbs".
  6. Create a shortcut for the CheckLogSendTo.vbs file. Rename it as "CheckLog".
  7. Copy the shortcut to the user's SendTo files here: C:\Documents and Settings\%USERNAME%\SendTo, replacing the %USERNAME% variable with the username in question.
  8. Right click on a file or directory to check. Go to Send To > CheckLog.
  9. Select Yes, No, or Cancel when asked whether you would like to add additional arguments.
    1. Yes = Add arguments
    2. No = Use the default arguments
    3. Cancel = Cancel the check
  10. If you said Yes above, enter the additional arguments you would like to use. See the Arguments page for more detail.
Here are some screenshots of the script in action:


Note: VBScript is required, which is unfortunately only available on Microsoft Windows. I hope to develop a platform-independent script sometime. I chose VBScript because it required no additional installation or administrator requirements on the platform I current work on.

This script should save me a lot of time! Normally I would copy the directory and filename of the log into a SAS session and paste it into a CheckLog call. But now it's more automatic, and I get the results faster.

Please feel free to send me feedback about the script!

Tuesday, November 15, 2011

SAS and Ampersands

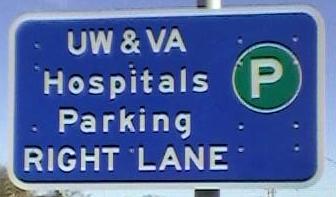
I realized I'm a SAS geek today. On my way to work, near the UW and VA hospitals, I saw a street sign that displayed "UW&VA" and I wondered, "What does &VA resolve to?"

Road sign: 'UW&VA Hospitals Parking Right Lane'
What does &VA resolve to?

So you know when you're a SAS geek when you see a sign with an ampersand immediately followed by characters, and wonder, "What does that resolve to?" Bad joke, go to your work library!

Seriously, though, this brings up a good topic: How do you resolve macro variables with special characters in the value? For example, if we have the macro variable parking_sign with the value "UW&VA", and this value is assigned automatically in a data step using the CALL SYMPUT routine or SQL using the INTO statement, neither of which would generate an error in the log regarding the value of the macro variable VA.

There are a couple of solutions to solve this and avoid an error in the log:
  1. Define the macro variable VA as "VA" (i.e., %let va=VA;). This is a quick fix that allows the process to continue by creating a value for the macro variable that the code is mistakenly trying to look up. But it does not solve the problem completely, since new strings with ampersands or even percent signs could be introduced into your source data. This process could be automated to generate multiple macro variables for each string with an ampersand found, but it would not work for macro programs (which use percent signs).
  2. Edit the source data and mask the characters after the ampersand (or percent sign) with the %STR (or related) function. This solution would work, but it would be rather awkward, and your source data would have a strange-looking value (i.e. "UW&%str(V)A"), which might not be a good solution if you have to use the data in a different way later, in which the %STR function would not execute, leaving the odd-looking raw value. It gets even more complicated when percent signs are involved.
  3. Instead of resolving the macro variable with the ampersand, resolve it with the %SUPERQ function. This function is a better solution, since it avoids any special characters problems and does not edit the source. Basically it tells SAS to resolve only the first level of the macro variable, and no further. However, it is not as easy to implement, since it requires replacing all references to the macro variable (e.g., &PARKING_SIGN) with different code (i.e., %SUPERQ(PARKING_SIGN));
  4. Use the %SUPERQ function with an additional step that redefines the PARKING_SIGN macro variable (see below). This is the best solution, since the rest of the code does not have to be re-written. The %LET statement is used to immediately redefine the macro variable using the %SUPERQ function, which will not resolve the values any further. Better yet, this is only one line of very simple code, and it fixes the problem forever!
/* Dummy data */
data test;
    input parking_sign $;
    format parking_sign $15.;
    infile datalines;
datalines;
UW&VA
;
run;

/* Generate macro variable */
data _null_;
    set test;
    call symputx('parking_sign', parking_sign);
run;

/* Use macro variable by writing it to the log. */
/* Note: Generates a (w)arning on the first run. */
%put &PARKING_SIGN;

/* Solution: Redefine macro variable */
%let parking_sign=%superq(PARKING_SIGN);

/* Use macro variable by writing it to the log. */
/* Note: This time there is no (w)arning. */
%put &PARKING_SIGN;

This last solution is by far the simplest and least amount of work to fix the problem.

For more on macro variable quoting (the %STR and %SUPERQ functions), see the SAS website:

http://support.sas.com/documentation/cdl/en/mcrolref/61885/HTML/default/viewer.htm#tw3514-overvwqt.htm

Saturday, November 12, 2011

A New SAS Tool for Checking the Log

SAS just released a new tool for checking the SAS log:

SAS Log Error Checking Tool

It only works on Windows, requiring the .NET framework, and it appears to be a separate executable from the usual SAS program. Further, it seems to only check for ERROR and WARNING messages.

As I've written before, I have a macro, CheckLog, that checks the log, too, and it runs on any operating system, can be used within a current interactive SAS session, and it appears to check for more messages. (See the CheckLog About page for more documentation.)

If anyone tries out SAS's tool, I'd love to hear a comparison of the capabilities!

Monday, September 12, 2011

SAS Passwords Suck

There, I said it. Apparently anyone else who uses SAS passwords hasn't had the guts to say that. Here's why I say so:
  • SAS data set passwords must adhere to the rules for SAS names. These rules include:
    • The first character must be a letter or the underscore (1)
    • All other characters can be letters, numbers, or the underscore (1)
    • The length cannot exceed 8 characters (2)
  • Using PROC SQL, programmers can enter longer passwords than are acceptable, without any notification (unlike in the DATA step), and these passwords become truncated. This lets the programmer think they are applying good passwords. Worse, if someone else has to use the password other than the programmer who created it, they will find it is broken and will not be able to continue with their work.
  • There is an option to encode passwords, but as the SAS documentation notes (3): "With encoding, one character set is translated to another character set through some form of table lookup. An encoded password is intended to prevent casual, non-malicious viewing of passwords. You should not depend on encoded passwords for all your data security needs; a determined and knowledgeable attacker can decode the encoded passwords." So I'm not quite sure what the point is of such an option, since it's easily hacked.
  • SAS data set passwords are typically stored as plain text within SAS code. For anyone who wants to get the password, find the source code. Usually the directory is not secured in the OS.
  • If the password is incorrect, a pop-up appears, which can be turned off (4). So a hacker could turn off the option and keep cycling through passwords until the correct one is reached.
  • Requiring passwords on data sets implies that other, standard systems of securing and backing up data are not trusted; furthermore, it conveys a level of distrust for the SAS programmers who are using the data sets. Other than human error, what is a well-meaning SAS programmer going to do with the data?
Someone out there might say, why not use data set generations (5)? (Generations are basically automatic copies of SAS data sets that have a limit on the number of copies.) There are several reasons against this:
  1. It's a waste of disk space, especially with large data sets, and especially if you have a good backup system.
  2. The generations are eventually deleted. Once an item reaches the maximum number, it's deleted. If that data set was important, why would you want to delete it, ever?
  3. It's confusing. There are no explicit explanation of what a generation may mean. It could be that one value was off in one generation so the data had to be re-run. It could be the whole data set was the wrong one. Why would you want to keep a history of that? It's simply garbage.
So what's a SAS administrator to do? First, use the operating system to manage rights by folder access. If only certain people should access the SAS data sets and code, lock the files for only those users. Second, implement good OS password policies. Those passwords can be by far better than SAS's! Third, back up hard drives automatically. Fourth, set a coding standard for making backups/copies in SAS before overwriting important data sets, which simply makes it easier to restore from a bad run (instead of finding the actual backup). (The DATASETS procedure is great for bulk copying and modifying SAS data sets.) Fifth, trust your programmers. If you can't trust your programmers, why are they working for you? Why do you give them important work? Do you really want to convey that to them? What does it do for their morale and self worth?

I hope by posting this SAS realizes that their password mechanism is essentially broken and useless. Even a novice hacker could figure out how to break into such a system. Other options in the system don't really help, which leads back to the OS itself. And the OS probably has much better tools for managing access and passwords that SAS does.

References
  1. http://support.sas.com/documentation/cdl/en/lrcon/62955/HTML/default/viewer.htm#a001028606.htm
  2. http://support.sas.com/documentation/cdl/en/lrcon/62955/HTML/default/viewer.htm#a000998953.htm#a000998960
  3. http://support.sas.com/documentation/cdl/en/lrcon/62955/HTML/default/viewer.htm#a003166704.htm
  4. http://support.sas.com/documentation/cdl/en/lrcon/62955/HTML/default/viewer.htm#a000995314.htm
  5. http://support.sas.com/documentation/cdl/en/lrdict/64316/HTML/default/viewer.htm#a000243174.htm

Sunday, August 7, 2011

Writing a Portable SAS Macro

One aspect of writing macros for SAS is to try to make them portable. There are two aspects of this: First, writing the process in a manner that is generalizable so that there's a need for the macro to be portable; second, writing the program so it works on multiple platforms of SAS and operating systems (OS).

The first task I've always seemed to excel at. With almost 90 general-use macros hosted on my site, I have a macro for many useful, reusable processes. I've written code with these macros where most of the code is simply calls to these macros. They save a lot of time and repetitious code.

The second task, however, has always been a bit elusive, especially since I am unable to run my macros on different OSs. A SAS license would be required on each OS to do so, even if I had UNIX, z/OS, OpenVMS, and Windows installed where I could access them. This creates some significant problems with this last task. As a result, I have come up with a few strategies to get around the issue.

The first and most powerful is to re-write any OS-specific function or process in the native SAS language. This can be tricky since a simple process like obtaining a list of files in a directory can be a simple, one-line piece of code for the OS, but several steps (and sometimes more limited functionality) for SAS.

Another step is to simply modify the macro to run several different versions of the same thing depending on the OS. SAS has two automatic macro variables that define the operating system, SYSSCP and SYSSCPL, that can be used to run conditional code that will work in the OS. This is still tricky, since I have no way to test the code to see if it works. It helps to review help documentation, examples online, and forums for those OSs, but I'm still never 100% certain that it will work as expected.

For this last part, I rely on the users out there. I received several rounds of feedback recently on my CheckLog macro, which reviews the SAS log, an external log (even non-SAS), and an entire directory of logs, with several additional features to tweak how it runs and how it notifies the user about issues. (See the documentation for more detail.) These users were able to provide specific feedback about what didn't work, and they were able to test new versions on their system quickly. Through this process, I was able to modify the macro significantly, and now it runs on all SAS-supported OSs (UNIX, z/OS, OpenVMS, and Windows). And the users have a better utility that fits their needs with insignificant cost.

Using this model for developing macros, it could be possible to add to the standard SAS library with new and very useful processes. So if you're a SAS user, join in and contribute to the community by publishing general-use macros or by testing and providing feedback to others who have done so!

Tuesday, July 12, 2011

News and Advice

Last week, I started a new position with the Health Innovation Program in the School of Medicine and Public Health at the University of Wisconsin-Madison. In this position, I hope to be more involved in research that could potentially affect patient care. Ever since my days doing academic and educational research, I have missed being involved in the process.

Along with this transition, it appears I've started to become a help desk of sorts for some SAS. I received two sets of email from different users of my macros, and I thought I would start sharing those questions and answers here:

Question 1:

Is there a way to limit the number of observations read by PROC IMPORT? I tried using OPTIONS OBS=2 before proc import and it worked but still the reduction in time was not significant.

Answer 1:

It depends on the file, so you'd have to look at the IMPORT procedure documentation depending on what you're importing to see if that feature is available.

Where did you put the option? It must have been just above the output. If so, then yes, it wouldn't decrease the time, since SAS is still pulling in all of the records. Depending on the location of the option, SAS may only keep the number of records on its way out of the import process. Either way, SAS may need to read the entire file, which would reduce time.

What if you tried just pulling in the header record, and delimiting them yourself? I'm guessing you're looking at comma-delimited, space-delimited, or tab-delimited data, and you should be able to figure out how to read the data in as one record, then split the variable names into multiple variables or even records. Then you could see if there are any new records.

Question 2:

Kindly help me to create the folders using SAS codes in local drive or on server without using X-command.

Answer 2:

You can use either CALL SYSTEM within a data step or %SYSEXEC. You'll want to tinker with the XSYNC and XWAIT options as you see fit. Here are two examples:

data _null_;
    call system('md c:\TestDir');
run;

OR

%sysexec(md c:\TestDir\);

Monday, June 13, 2011

Unusual SAS Error Message

Today I encountered the following error messages in SAS after creating a table using SQL based on a SASHelp table:

ERROR: Floating Point Zero Divide.
ERROR: Termination due to Floating Point Exception

This strange set of errors is not well documented and, as I eventually found out, has nothing to do with my original query:

proc sql;
create table _test_ as
select * from sashelp.vtable
where upcase(libname)="SPECIFIC_LIBNAME"
;
quit;

Where "SPECIFIC_LIBNAME" was a macro variable containing the libname I wanted information about.

The solution to this problem was to clear a particular library that consisted only of views. This library's members were generated prior to the above step, and may have somehow contributed to the problem within the SASHelp metadata. In general, it may be a good practice to review the libraries and their sizes when encountering problems with the SASHelp library, which contains a great deal of metadata on SAS libraries.

For this set of errors, however, this solution will probably not always work. It would appear that the problem is related to extensions of SAS that are dependent on external sources. In this case, it may have been the SQL procedure. This does seem strange, since SQL is a widely-used standard. Clearing the previously-created library may have cleared up an exception caused by a large amount of data in the SASHelp table that was not accounted for in the manner in which SAS implemented the SQL standard or the proprietary extensions of it.

If you encounter this error, please let me know! Especially if you know how to fix it!

Articles and Discussions Regarding these Errors:

Friday, April 8, 2011

Recipe Database

I've been working on a recipe database for my wife, to help her plan meals by being able to easily peruse recipes (especially favorite recipes) and associate those recipes with days and meals. I also wanted to be able to easily add recipes, ingredients, and grocery items. Here is the most recent relationship view of the database:


Each recipe is associated with a list of directions and a list of ingredients. Since ingredients are variations on specific items, they are not distinct grocery list items. For example, one recipe may call for 2 tomatoes and another may call for 3 tomatoes, and each would be a separate ingredient, but only one grocery item with a combined total of 5 units. Grocery items also have alternatives in a self-referential link (ALT_GROC_ID), which would be appropriate for recipes with "or"s in the ingredient list or legitimate alternatives (e.g., sea salt for salt).

Then there are the weekly plans, called "Lists". I realized this term may cause some confusion between grocery lists and plans, so I may change it in the future. For now, I'm focusing on completing the functionality of the database and not improvements to the delivery. Each list is associated with a beginning and end date ("from" and "thru" on the Lists table). Each list has several detail lines in the Lists_detail table that associates days with meals for the days between the beginning and end dates, inclusively. Each meal is then related to a recipe.

Currently the database exists in a Microsoft Access database, and eventually I would like to port it over to SQLite or something similar, with HTML forms. For now, there are several Access forms for data entry, and the initial "Start" form that opens with the database provides access to many of those forms.


The top section of buttons appends new plans to the Lists table with different start dates. For a typical week, a user might start planning on Saturday for the next week Sunday - Saturday and the following week Sunday - Saturday, and would thus start two new lists using the Tomorrow and "Week from Tomorrow" buttons. The two new lists would be associated with today's date, which is displayed in the upper right hand corner.

Once the new lists are initiated, the user can open them by using the "Today's Plans" button in the "Open..." section. The user can also open recipes for viewing and the grocery list based on today's plans. Eventually I'm going to switch the grocery list from a view-only report to a form based on an append query, which would keep track of the lists through time and build an inventory of the kitchen. (This is where the confusion with "lists" would come in to play.) Also from the start form, the user can also add or edit recipes, add or edit grocery items, or delete plans.

The main function of the database is to help the user plan for a week or two of meals by associating days and meals with recipes and ultimately generating a list of grocery items to use while shopping. Here is the plan entry form (click for a larger view) that opens when the "Today's Plans" button is used:


The list date range is the first section, with arrows allowing the user to switch lists. The navigable lists depends on how the user opened the form based on the buttons in the start form. The user then uses the drop-down boxes to select days and meals. Next, the user can use the bottom part of the form to look up recipes. Say the user wants a rice dish, so the user clicks on the binoculars and searches the Name field for "rice". Currently there are fields for descriptions, authors, origins, and URLs for recipes, which could also be added to the form to help the user find a particular recipe.

The ingredients and directions are listed to help the user figure out what would be appropriate to prepare for any given day's plan. Once the recipe is selected, the user enters the recipe ID next to the meal. Alternatively, the user can enter something other than a recipe for a meal, for example, "go out to eat with friends" or "order pizza". Once the weekly plan(s) are complete, the user can return to the start form and open the grocery list report, which is organized by the location the items are found in the store, like produce, meats, aisles, etc.:


There is a lot of work still to do. As I mentioned, I have to figure out how to append the grocery lists to a list table to maintain a history. Then, I need to enter a lot of recipes. The recipes in the database currently were entered using a SAS program and borrowing work's SAS server to process it. The next recipes will be entered using the new form as a test run of how well it works. I expect I will revise the form quite a bit to make it flow better. I also have to figure out how to merge disparate measurements, e.g., cups and ounces, and only display a total quantity on the grocery list. Some merges will not be possible, as the above image shows for kosher salt: 7.5 tsp and "to taste". (Note the odd "40 taste" - this is a conversion of the ingredient "8 dashes of hot sauce", which is unquantifiable, and the dummy records I entered had 5 of the same recipe, thus "40 taste".) Then there's the conversion into a "better" database tool and using web forms instead of these proprietary-format forms.

For now, though, I am very happy that the database, although not fully populated with recipes, is usable and can save the user (just my wife, for now) a lot of time.

Wednesday, March 16, 2011

SAS Macros versus Python Functions, Part 1

I recently started reading Dive Into Python, a primer to the programming language Python (which I converted to MOBI and loaded onto my Kindle - available here), and I was delightfully surprised how similar functions are to the SAS macro. Here are some examples:

First, the very first line of a function or macro, that defines it as a function/macro, is very similar. In Python, one would write:

def buildConnectionString(params):

In SAS, it is very similar:

%macro buildConnectionString(params);

The terms def and %macro begin the code by stating what follow: a function definition or a macro. The "buildConnectionString" is the name of the function/macro, and enclosed in parentheses are the function/macro parameters or arguments, separated by commas.

Second, it is often a good idea to have some documentation on the function/macro. In Python, the documentation is stored in a doc string; in SAS, a very short and not as useful description string is available:

def buildConnectionString(params):
    """Build a connection string from a dictionary of parameters.

    Returns a string."""


SAS:

%macro buildConnectionString(params) / des="Build connection string. Returns string.";

UPDATE: I'm not sure where I learned the 40-character limit mentioned below, but I just read in the SAS help documentation that the limit is 256 characters. Nonetheless, reading the description is still limited by screen space, so the alternatives I mentioned here are still very useful.

Unfortunately, SAS macros are limited to 40 256 characters in the description. This can be worked around by offering HELP as a valid value to the first argument, which then outputs additional information about the macro. My macros are documented in a spreadsheet, and I have a macro (ArgList) that reads in the spreadsheet and outputs additional details about the arguments when I need it. One day, I would like to convert all of my macros to use a standard header that contains the information about the arguments, its purpose, and other details in a standard way so I can modify the ArgList macro to read the macro itself instead of external documentation. In Python, though, the doc string can be viewed when referencing the function, on the fly. That's incredibly useful, and much more flexible than SAS.

One area of difference is the syntax and the meaning of space: In all Python code, space has meaning, whereas in SAS code in general, it does not. Even so, I typically indent my SAS code just like Python code requires (in most cases - I try to maintain readability, too).

Once I learn more about Python, I'll post more comparisons!